CytoDataFrame#


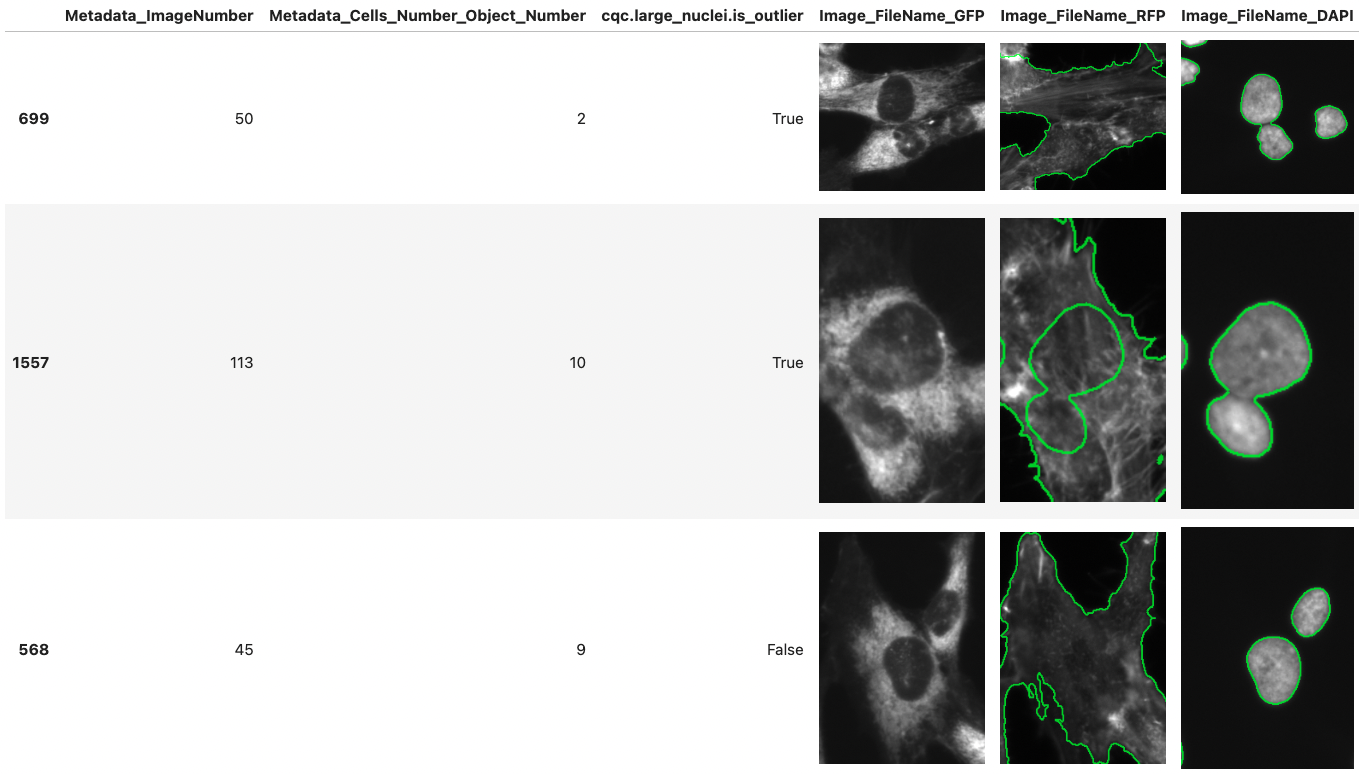 CytoDataFrame extends Pandas functionality to help display single-cell profile data alongside related images.
CytoDataFrame is an advanced in-memory data analysis format designed for single-cell profiling, integrating not only the data profiles but also their corresponding microscopy images and segmentation masks. Traditional single-cell profiling often excludes the associated images from analysis, limiting the scope of research. CytoDataFrame bridges this gap, offering a purpose-built solution for comprehensive analysis that incorporates both the data and images, empowering more detailed and visual insights in single-cell research.
CytoDataFrame is best suited for work within Jupyter notebooks. With CytoDataFrame you can:
View image objects alongside their feature data using a Pandas DataFrame-like interface.
Highlight image objects using mask or outline files to understand their segmentation.
Merge multiple channels into a single single-cell crop composite (similar to a Fiji composite) with
display_options={"composite_channels": "all"}or a per-channel color mapping such asdisplay_options={"composite_channels": {"OrigDNA": "cyan", "OrigRNA": "#ff00ff"}}(colors may be names, hex codes, or RGB tuples; cyan/magenta/yellow read more clearly than red/green/blue where channels overlap). A color legend is shown with the table, anddisplay_options={"equalize_clip_limit": 0.01}gives a milder, less over-saturated result.Adjust image displays on-the-fly using interactive slider widgets.
Display image objects even when bounding box columns are missing, by cropping from compartment-center offsets or rendering whole fields of view.
Automatically detect 3D image volumes and render interactive trame views in notebooks when 3D dependencies are installed (with graceful fallback otherwise).
Interoperate with the Polars and Apache Arrow ecosystems while keeping the familiar Pandas-based experience.
Polars and Arrow interoperability#
CytoDataFrame uses Apache Arrow as its canonical schema/interchange contract. Polars is the execution engine for lazy/scalable queries. Pandas remains the compatibility layer that CytoDataFrame itself is built on. You can move between all three representations, and run lazy queries, without leaving the CytoDataFrame API:
from cytodataframe import CytoDataFrame

# Construct from pandas, polars (DataFrame or LazyFrame), or a pyarrow Table.
cdf = CytoDataFrame("profiles.parquet")

# Convert to any representation. Pandas is CytoDataFrame's compatibility
# boundary (CytoDataFrame is a pandas.DataFrame subclass internally), so
# `to_pandas()` just returns a plain, un-subclassed pandas.DataFrame view of
# the same data; the other `to_*` calls convert it into that library's type.
cdf.to_pandas()  # pandas.DataFrame
cdf.to_polars()  # polars.DataFrame
cdf.to_arrow()  # pyarrow.Table
cdf.to_lazy()  # CytoLazyFrame (lazy, Polars-backed)

# Inspect the inferred schema (metadata / feature / geometry roles), e.g.:
# CytoSchema(image_key='Image_FileName_DNA', object_key='Metadata_ObjectNumber',
#            metadata_columns=[...], feature_columns=[...],
#            geometry_columns=[...], image_columns=['Image_FileName_DNA'])
cdf.cyto_schema
Large Parquet datasets can be scanned lazily rather than loaded into memory up
front. Polars only reads the rows/columns it actually needs once .collect()
runs (“predicate pushdown” for the .filter(...) row condition, “projection
pushdown” for the columns .select_features() keeps):
import polars as pl
from cytodataframe import CytoDataFrame

result = (
    CytoDataFrame.scan_parquet("profiles.parquet")
    .filter(pl.col("Metadata_Well") == "A01")
    .select_features()
    .collect()  # -> CytoDataFrame
)
For 3D notebook display behavior:
3D-aware rendering is enabled by default (
display_options={"auto_trame_for_3d": True}).Disable automatic trame switching with
display_options={"auto_trame_for_3d": False}.Force trame layout regardless of auto-detection with
display_options={"view": "trame"}.
For images without bounding box columns (e.g. older CellProfiler outputs or image-level data):
Crop from compartment-center coordinates plus pixel offsets with
display_options={"offset_bounding_box": {"x_min": -20, "y_min": -20, "x_max": 20, "y_max": 20}}(requires compartment center columns such asNuclei_Location_Center_X/Y).Render the full field of view without cropping with
display_options={"render_whole_image": True}(works even with no bounding box and no center columns).
For row display in notebook/widget tables:
CytoDataFrame respects pandas display settings (
display.max_rows,display.min_rows).When the table is larger than
display.max_rows, the widget table inserts a midpoint ellipsis row (…) to indicate omitted rows.You can control truncation behavior by changing pandas display options before rendering.
📓 Want to see CytoDataFrame in action? Check out our example notebook for a quick tour of its key features.
✨ CytoDataFrame development began within coSMicQC - a single-cell profile quality control package. Please check out our work there as well!
Installation#
Install CytoDataFrame from source using the following:
# install from pypi
pip install cytodataframe

# or install directly from source
pip install git+https://github.com/cytomining/CytoDataFrame.git
The core install is intentionally lean. Heavier, feature-specific stacks are available as optional extras:
# interactive 3D volume rendering (trame / pyvista)
pip install "cytodataframe[viz3d]"

# OME-Arrow image read/write/embedding (to_ome_parquet, OME-Arrow columns)
pip install "cytodataframe[ome]"

# everything
pip install "cytodataframe[all]"
Everything else in CytoDataFrame (including its Jupyter table/image display)
works without these extras. If you skip them, calling a feature that needs
one - to_ome_parquet(), or 3D rendering when pyvista/trame aren’t
installed - raises an error naming the missing package and the extra to
install, rather than failing silently.
Contributing, Development, and Testing#
Please see our contributing documentation for more details on contributions, development, and testing.